
The Scenario: It is 9:00 AM on Monday. Your Marketing Director needs to know “Which product category had the highest ROI in Q3?”
The Marketing Director sends a ticket to the Data Team.
The Data Team is backlog-deep in critical infrastructure work.
Three days later, a Junior Analyst writes a SQL query to pull the number.
Result: The decision is delayed by 72 hours because the people who need answers don’t speak the language of the database (SQL).
This is the Data Bottleneck. And for the first time in history, we can solve it without teaching everyone in the company how to code.
The Solution: LLMs as a Translation Layer
You don't need a "dashboard." You need an interpreter.
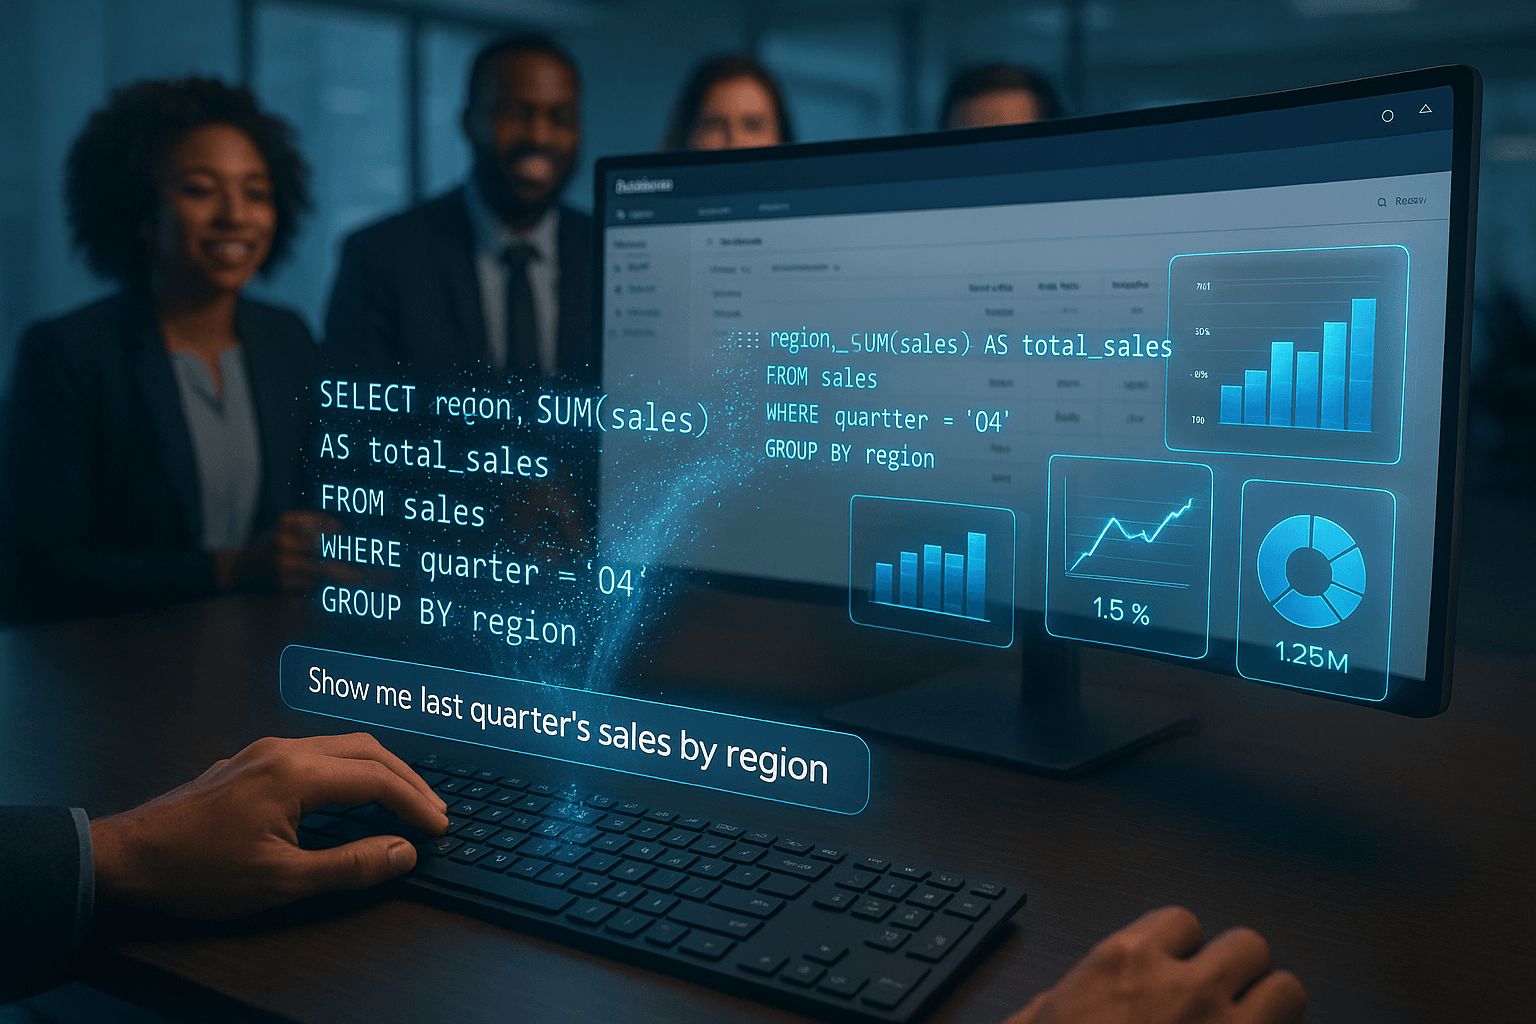
Large Language Models (LLMs) have mastered the ability to translate natural human intent into structured code. By architecting a "Text-to-SQL" pipeline, we can allow non-technical staff to chat with your PostgreSQL, MySQL, or Snowflake databases directly.
Here is how the translation workflow looks in practice:
User Input: "Show me total sales for Q3, grouped by region."
The AI Layer: The model analyzes your database schema and understands that "sales" refers to the revenue column and "region" refers to the geo_location table.
The Output (Hidden): The AI generates and executes:
SELECT region, SUM(revenue) FROM sales_data WHERE quarter = 'Q3' GROUP BY region;
The Result (Visible): The user sees a clean chart or table answering their question instantly.
The Tech Stack: How We Build It
You cannot simply "plug ChatGPT" into your private database. That is a security nightmare. Building a production-grade Text-to-SQL agent requires a specific stack to handle context and schema mapping.
1. The "Brain" (The Model)
We typically utilize OpenAI’s GPT-4o or Claude 3.5 Sonnet via API. These models have high reasoning capabilities, allowing them to understand complex SQL logic like JOINS and nested queries better than smaller open-source models.
2. The Orchestration (LangChain & LlamaIndex)
Raw LLMs don't know what your database looks like. We use orchestration frameworks like LangChain or LlamaIndex to "feed" the AI the context it needs without exposing your actual data.
- LlamaIndex is particularly powerful here. It indexes your database metadata (table names, column types) so the AI knows how to write the query, without the AI ever needing to read the sensitive rows of customer data.
3. Execution & Function Calling
Using OpenAI Function Calling, we structure the output so the AI doesn't just "talk"; it executes code in a controlled environment. This ensures the output is always valid JSON or SQL, preventing the system from breaking when the user asks a weird question.
The Risks: Why "Out of the Box" Fails
If you just connect an LLM to your database, you risk two major issues:
1. Hallucinations: The AI might invent column names that don't exist, causing the query to fail.
Destructive Queries: Imagine a user asks, "Remove the old data." If not properly gated, the AI might execute a DROP TABLE command.
2. Destructive Queries: Imagine a user asks, "Remove the old data." If not properly gated, the AI might execute a DROP TABLE command.
Next Steps: Architecting for Safety
To make this work in a business environment, you need Read-Only permissions, Schema limitation (only showing the AI the tables it needs), and a Self-Correction Loop (where the AI fixes its own code if the database throws an error).
Building a reliable Text-to-SQL system requires guardrails so the AI doesn't hallucinate. If you need help architecting this, check out our Service.